BIRD Bench research reveals that well-structured data models achieve 95% SQL generation accuracy — without semantic layer tools
Your Data Model Is the Semantic Layer: Why Clean Metadata Beats AI Wrappers
BIRD Bench research reveals that well-structured data models achieve 95% SQL generation accuracy — without semantic layer tools
The Surprising Finding
MotherDuck’s analysis of the BIRD Benchmark — a rigorous SQL generation test — reveals a counterintuitive truth:
“AI-ready data simply means a clean data model. Well-named tables, straightforward joins, and clear column names are enough for frontier LLMs to achieve 95% accuracy on SQL generation.”
Not RAG. Not vector stores. Not semantic layers. Just good data modeling.

The Numbers Tell the Story
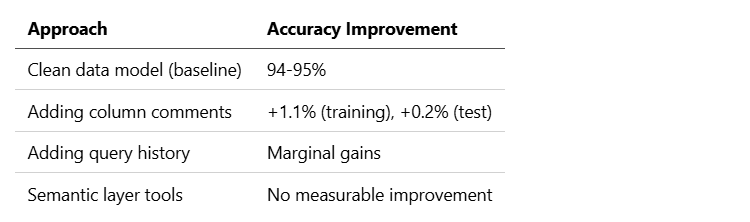
The research found that column comments actually hurt performance on schemas with intuitive naming. Over-documentation confused the LLM more than it helped.
What LLMs Actually Need
The research identifies the structural characteristics that enable high SQL generation accuracy:
Do This

Don’t Do This

The Documentation Paradox
Here’s the counterintuitive finding: document only what’s genuinely confusing.
-- BAD: Over-documentation
-- Column: customer_id
-- Description: The unique identifier for the customer
-- Type: INTEGER
-- This field uniquely identifies each customer record

-- GOOD: Document business rules only
-- Column: status_code
-- Values: 1=pending, 2=approved, 3=rejected, 7=completed (legacy)
When column names are self-explanatory (customer_name, order_date, total_amount), adding descriptions creates noise. LLMs parse the schema directly—redundant comments dilute signal with noise.
Document the non-obvious :
- Business-specific codes and enums
- Legacy patterns that contradict naming
- Domain-specific calculations
- Historical quirks
Implications for Data Architecture
Rethinking the Semantic Layer
Traditional semantic layers promise to abstract complexity:
Raw Tables → Semantic Layer → Business Terms → LLM → SQL
The research suggests a simpler path:
Well-Modeled Tables → LLM → SQL
If your data model is the semantic layer, you eliminate:
- Translation overhead
- Sync issues between layers
- Additional tooling complexity
- Semantic drift
The One Big Table (OBT) Advantage
For AI use cases, denormalization may actually improve accuracy:
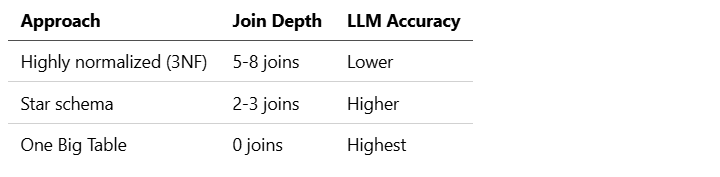
The OBT pattern — pre-joining dimensions into wide tables — gives LLMs exactly what they need: a single table with all relevant columns and clear names.
MDDE’s Approach: Metadata as AI Infrastructure
This research validates MDDE’s core philosophy: metadata isn’t overhead — it’s infrastructure.
Clean Naming Through Stereotypes
MDDE stereotypes enforce naming conventions:
stereotype_id: dim_scd2
naming_pattern: "dim_{entity_name}"
required_columns:
  - valid_from
  - valid_to
  - is_current
Result: Every SCD2 dimension follows predictable patterns. LLMs learn the pattern once.
Explicit Relationships
relationships:
  - from_entity: order
    to_entity: customer
    cardinality: many_to_one
    join_key: customer_id
No guessing. No ambiguity. The LLM knows exactly how to join.
Strategic Documentation
MDDE’s @mdde-description annotation encourages documenting intent , not obvious structure :
-- @mdde-description: Order status uses legacy codes: 7=completed (migrated from v1 system)
SELECT
    order_id,           -- @pk
    customer_id,        -- @fk(customer.id)
    status_code,        -- @domain(order_status)
    order_date,
    total_amount        -- @decimal(18,2)
FROM ...
Practical Recommendations
1. Audit Your Naming
Run this query against your metadata:
SELECT
    entity_name,
    CASE
        WHEN LENGTH(entity_name) < 5 THEN 'Too short (cryptic)'
        WHEN entity_name LIKE '%[0-9]%' THEN 'Contains numbers (version suffix?)'
        WHEN entity_name NOT LIKE '%_%' THEN 'No word separation'
        ELSE 'OK'
    END AS naming_issue
FROM metadata.entity
WHERE naming_issue != 'OK';
2. Measure Join Depth
WITH RECURSIVE lineage AS (
    SELECT entity_id, entity_name, 0 AS depth
    FROM metadata.entity
    WHERE layer = 'business'

UNION ALL
    SELECT e.entity_id, e.entity_name, l.depth + 1
    FROM metadata.entity_mapping em
    JOIN metadata.entity e ON em.source_entity_id = e.entity_id
    JOIN lineage l ON em.consumer_entity_id = l.entity_id
    WHERE l.depth < 10
)
SELECT entity_name, MAX(depth) AS max_join_depth
FROM lineage
GROUP BY entity_name
HAVING MAX(depth) > 3
ORDER BY max_join_depth DESC;
3. Identify Undocumented Business Rules
SELECT
    e.entity_name,
    a.attribute_name,
    a.data_type
FROM metadata.attribute a
JOIN metadata.entity e ON a.entity_id = e.entity_id
WHERE a.attribute_name LIKE '%code%'
   OR a.attribute_name LIKE '%status%'
   OR a.attribute_name LIKE '%type%'
AND (a.description IS NULL OR a.description = '');
These are your high-value documentation targets.
4. Consider Pre-Joined Views
For AI query endpoints, create OBT-style views:
-- @mdde-entity: customer_360_obt
-- @mdde-stereotype: obt_table
-- @mdde-description: Pre-joined customer view optimized for AI queries

SELECT
    c.customer_id,
    c.customer_name,
    c.email,
    o.total_orders,
    o.lifetime_value,
    p.preferred_category,
    s.customer_segment
FROM dim_customer c
LEFT JOIN fact_customer_orders o ON c.customer_id = o.customer_id
LEFT JOIN customer_preferences p ON c.customer_id = p.customer_id
LEFT JOIN customer_segments s ON c.customer_id = s.customer_id;
Zero joins for the LLM. Maximum accuracy.
The Meta-Point: Design for AI Now
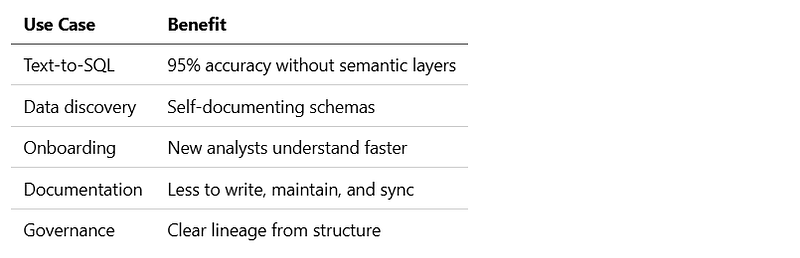
Every table you create today will eventually be queried by AI. The question isn’t whether to optimize for LLMs — it’s when.
The investment in clean data modeling pays dividends across:
Key Takeaways
- Clean data models ARE semantic layers for AI purposes
- Over-documentation hurts LLM performance on intuitive schemas
- Document only the non-obvious : business rules, legacy patterns, domain codes
- Minimize join depth to improve SQL generation accuracy
- Consider OBT patterns for AI query endpoints
- Naming matters more than comments for LLM comprehension
The future of data access is AI-mediated. Your data model is your interface.
Further Reading
- BIRD Benchmark — SQL generation evaluation
- MotherDuck Research — Original analysis
Inspired by MotherDuck’s BIRD Bench analysis.