When someone asks “What breaks if we change this?”, you shouldn’t need a graph UI and a magnifying glass. Reverse lineage + a tidy Excel is enough.
Why product owners need impact analysis
Changing a column, renaming a table, or altering a transformation shouldn’t feel risky. Yet most teams still debate the blast radius. Catalogs can show upstream/downstream graphs, but they’re not the fastest way for a product owner to answer:
Who consumes this field? Where will a change ripple?
Our approach from Article 1 — a lineage delivery layer in DuckDB — also solves impact analysis with one simple twist.
The one twist: reverse the join
Lineage (source → target) and impact (target → source) use the same recursive query and metadata. Just flip the mapping direction.
Lineage expands from current → children on source = current
Impact expands from current → parents on target = current
-- IMPACT (reverse): walk from a target upward to its sources
JOIN column_mapping cm
  ON cm.target_schema = w.to_schema
 AND cm.target_table  = w.to_table
 AND cm.target_column = w.to_column
Everything else stays the same:
depthfor indentorder_keylike1.2.3for perfect Excel sorting- a simple cycle guard (visited path)

Reverse Impact: highlight a changed field and follow arrows upstream to see who breaks.
Unified delivery table (both directions)
Keep one table (lineage_analysis) with a direction flag so business users can filter:
Press enter or click to view image in full size
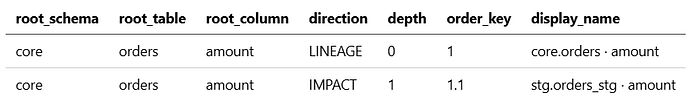
In Excel:
- Filter
direction = IMPACT - Sort by
order_key - Scan
display_nameto see upstream dependencies

ilter by _direction_, sort by _order_key_, and follow the indented _display_name_.
Ready-to-run SQL snippets
Seed a root (what you plan to change):
-- Example root we’re assessing
PRAGMA vardict_set('root_schema', 'core');
PRAGMA vardict_set('root_table',  'orders');
PRAGMA vardict_set('root_column', 'amount');
Reverse (IMPACT) traversal (column-level):
WITH RECURSIVE
seed AS (
  SELECT
    'COLUMN' AS root_kind,
    getvariable('root_schema') AS root_schema,
    getvariable('root_table')  AS root_table,
    getvariable('root_column') AS root_column,
    0 AS depth,
    '1' AS order_key,
    -- from == to at the root
    getvariable('root_schema') AS from_schema,
    getvariable('root_table')  AS from_table,
    getvariable('root_column') AS from_column,
    getvariable('root_schema') AS to_schema,
    getvariable('root_table')  AS to_table,
    getvariable('root_column') AS to_column,
    CONCAT_WS('.', getvariable('root_schema'), getvariable('root_table'), getvariable('root_column')) AS visited
),
walk AS (
  SELECT * FROM seed
  UNION ALL
  SELECT
    w.root_kind, w.root_schema, w.root_table, w.root_column,
    w.depth + 1 AS depth,
    w.order_key || '.' ||
      CAST(ROW_NUMBER() OVER (
        PARTITION BY w.order_key
        ORDER BY cm.source_schema, cm.source_table, cm.source_column
      ) AS TEXT) AS order_key,
    -- reverse edge: from current node to upstream sources
    cm.target_schema, cm.target_table, cm.target_column,
    cm.source_schema, cm.source_table, cm.source_column,
    w.visited || '>' || CONCAT_WS('.', cm.source_schema, cm.source_table, cm.source_column)
  FROM walk w
  JOIN column_mapping cm
    ON cm.target_schema = w.to_schema
   AND cm.target_table  = w.to_table
   AND cm.target_column = w.to_column
  WHERE INSTR(w.visited, CONCAT_WS('.', cm.source_schema, cm.source_table, cm.source_column)) = 0
    AND w.depth < 50
)
INSERT INTO lineage_analysis
SELECT
  root_kind, root_schema, root_table, root_column,
  'IMPACT' AS direction, depth, order_key,
  from_schema, from_table, from_column,
  to_schema,   to_table,   to_column
FROM walk
ORDER BY order_key;
Swap the join (source = current) to compute forward LINEAGE.
Bulk-run for many roots (nightly job)
Pseudocode using DuckDB Python API
run_id = make_run_id()
all_cols = con.execute("""
  SELECT DISTINCT s, t, c
  FROM (
    SELECT source_schema s, source_table t, source_column c FROM column_mapping
    UNION
    SELECT target_schema, target_table, target_column FROM column_mapping
  )
""").fetchall(
for s, t, c in all_cols:
    run_column_walk(con, s, t, c, "LINEAGE", run_id)
    run_column_walk(con, s, t, c, "IMPACT",  run_id)
# Export a single XLSX, sorted by root + direction + order_key
Automate this in CI/CD and drop the XLSX to SharePoint/Teams for product owners.
Practical reading patterns for business users
- Change risk: filter
direction = IMPACT, search for the field you plan to change, and review the first two depth levels. - Dependency discovery: sort on
order_key, collapse bydepth, and skimdisplay_name. - Environment differences: add an
envcolumn to compare dev/test/prod impact side-by-side.
Wrap-up
Reverse lineage is the same engine as forward lineage — just point it upstream. By exporting a single, filterable Excel with direction, depth, and order_key, product owners can self-serve impact analysis without hopping into a graph.