Bringing documentation, governance, and business-friendly modeling to the dbt ecosystem.
Summary
dbt has transformed how analytics engineers build data pipelines: SQL-first, version-controlled, testable.
But as data environments scale, the challenge shifts: how do we keep hundreds of models understandable, documented, and aligned with the business?That’s where dbt-osmosis comes in — an open-source tool that synchronizes your dbt project with rich metadata and documentation.
For teams practicing model-driven data engineering and business-friendly, model-first approaches, dbt-osmosis is a key building block.
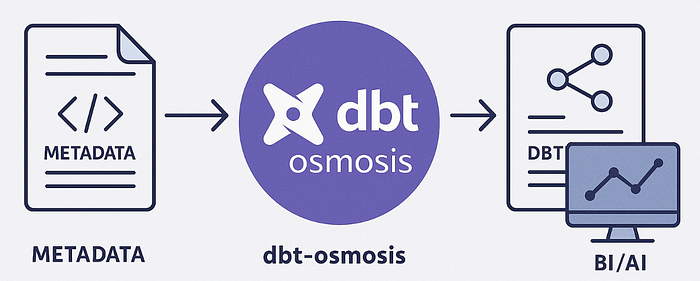
What Is dbt-osmosis?
dbt-osmosis is a documentation and metadata synchronization utility for dbt projects. It:
- Extracts dbt model definitions and generates or updates YAML documentation files.
- Synchronizes column-level metadata (descriptions, data types, tests) from your warehouse back into your dbt project.
- Cleans and organizes documentation for better readability and governance.
- Can integrate with external metadata systems or catalogs.
In other words: it keeps your dbt models and your metadata in sync — automatically.
Why dbt-osmosis Matters for Our Approach
Our methodology is metadata-first:
- Model-driven engineering: design your data structures and mappings centrally.
- Business-friendly mapping: ensure the business can read and influence models.
- Universal data models: use canonical, reusable patterns.
- Automation: generate diagrams, SQL, tests, and docs from metadata.
dbt-osmosis fits perfectly as the bridge between metadata-driven design and the dbt transformation layer.
How It Fits in Our Framework
Our high-level architecture:
Metadata Repository → Model-driven Design → dbt (Transform) → Delivery Layers (Semantic Views, BI)
- Metadata repository: YAML, JSON, or DuckDB holds canonical entities, attributes, mappings.
- Model-driven generation: scripts create dbt models (SQL + YAML).
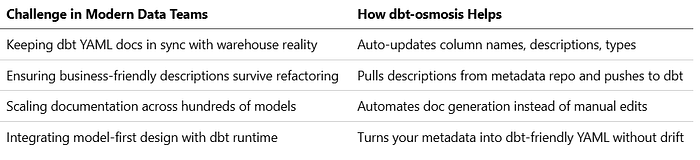
- dbt-osmosis: keeps dbt YAML documentation in sync when models change or when warehouse metadata evolves.
- Delivery: Semantic Views (Snowflake), BI, and AI tools consume well-documented, governed models.
With dbt-osmosis:
- We generate initial YAML from our metadata.
- We update docs automatically when schemas evolve.
- Business-friendly names and descriptions stay aligned — no more stale docs.
- Downstream consumers (BI, AI SQL generation) can trust the dbt metadata.
Practical Workflow
Model First
Define entities & mappings in metadata (YAML/DuckDB).
Generate dbt Artifacts
Scripts output dbt models (SQL) and starter YAML docs.
Run dbt-osmosis
- Pulls warehouse column info (data types, names).
- Merges business descriptions from metadata into dbt YAML.
- Cleans orphaned fields, ensures consistency.
Version & Commit
Docs evolve alongside code in Git.
Publish
Use dbt docs site, Semantic Views, or data catalog integration for discovery.
Example
Your metadata (YAML)
entity: customer
description: "A person or organization purchasing products."
attributes:
  - name: customer_id
    description: "Surrogate key for customer."
  - name: email
    description: "Primary contact email."
Generated dbt model: **models/marts/core/customer.sql**
select
    customer_id,
    email
from raw.customer;
dbt-osmosis sync → updates **models/marts/core/customer.yml**
version: 2
models:
  - name: customer
    description: "A person or organization purchasing products."
    columns:
      - name: customer_id
        description: "Surrogate key for customer."
      - name: email
        description: "Primary contact email."
Now the dbt docs site shows accurate, business-friendly descriptions — and stays updated as metadata or schema evolves.
Benefits in a Model-Driven Context
- Single Source of Truth: Metadata drives dbt docs, not the other way around.
- Zero Drift: Warehouse schema changes sync back automatically.
- Governed AI: LLMs generating SQL can use accurate dbt metadata.
- Less Manual Work: Engineers focus on transformations, not repetitive YAML edits.
- Consistent Business Language: The same terms flow from design to docs to BI.
Key Takeaways
- dbt-osmosis automates documentation and metadata alignment in dbt.
- It’s a natural fit for model-first, metadata-driven engineering.
- It closes the gap between design-time metadata and runtime dbt models.
- Well-documented models power self-service BI, governance, and AI SQL generation.
If you’re already investing in metadata-driven data engineering, adding dbt-osmosis removes one of the biggest friction points: keeping docs fresh and reliable at scale.