How auxiliary tables extend your data model without polluting your core schema
Sidecar Tables: Companion Metadata for Data Assets
** How auxiliary tables extend your data model without polluting your core schema**
Introduction
In data engineering, we often need to track information about our data that doesn’t belong in the data itself. History of changes. Quality scores. Audit trails. Load statistics. Version information.
The naive approach is to add columns directly to the main table:
created_at,updated_at,created_byquality_score,last_checked_atversion_number,previous_value
But this quickly becomes unwieldy. Your clean business entity becomes bloated with operational metadata. Your ETL pipelines now need to populate a dozen extra columns. Your consumers sift through fields they don’t care about.
Sidecar tables solve this by separating concerns: the main table holds business data, while companion tables hold operational metadata.
What is a Sidecar Table?
A sidecar table is a companion table that:
- References the main table via foreign key
- Tracks metadata that doesn’t belong in the main entity
- Has its own lifecycle (can be truncated, archived, or dropped independently)
- Follows naming conventions that make the relationship obvious
The term comes from the “sidecar pattern” in microservices architecture, where a helper container runs alongside the main application container, handling cross-cutting concerns like logging, monitoring, and security.
┌──────────────────────────────────────────────────────────────────────┐
│                          DATA ASSET                                  │
│                                                                      │
│   ┌─────────────────────┐     ┌─────────────────────────────────┐    │
│   │     Main Table      │     │        Sidecar Tables           │    │
│   │                     │     │                                 │    │
│   │  • Business data    │────►│  • _version   (SCD2 history)    │    │
│   │  • Core attributes  │     │  • _history   (change audit)    │    │
│   │  • Primary keys     │     │  • _quality   (DQ metrics)      │    │
│   │                     │     │  • _log       (load tracking)   │    │
│   └─────────────────────┘     │  • _audit     (access tracking) │    │
│                               │  • _config    (runtime params)  │    │
│                               └─────────────────────────────────┘    │
└──────────────────────────────────────────────────────────────────────┘
Sidecar Table Categories
1. Version Tables (_version)
Track the complete history of an entity using SCD Type 2 semantics.
Purpose : Answer “What did this record look like at time X?”
Structure :
entity_version:
  attributes:
    - version_id: VARCHAR (PK)
    - entity_id: VARCHAR (FK to main table)
    - version_sequence: INTEGER
    - valid_from: TIMESTAMP
    - valid_to: TIMESTAMP
    - is_current: BOOLEAN
    - changed_by: VARCHAR
    - change_reason: VARCHAR
    # ... snapshot of all versioned attributes
Example :
-- Main table
CREATE TABLE customer (
    customer_id VARCHAR PRIMARY KEY,
    name VARCHAR,
    email VARCHAR,
    segment VARCHAR
);

-- Version sidecar
CREATE TABLE customer_version (
    version_id VARCHAR PRIMARY KEY,
    customer_id VARCHAR REFERENCES customer(customer_id),
    version_sequence INTEGER,
    name VARCHAR,
    email VARCHAR,
    segment VARCHAR,
    valid_from TIMESTAMP,
    valid_to TIMESTAMP,
    is_current BOOLEAN,
    changed_by VARCHAR
);
When to use :
- Regulatory requirements for audit trails
- Time-travel queries
- Debugging data issues
2. History Tables (_history)
Track specific changes to attributes or status transitions.
Purpose : Answer “What changed, when, and why?”
Structure :
entity_status_history:
  attributes:
    - history_id: VARCHAR (PK)
    - entity_id: VARCHAR (FK)
    - status_dimension: VARCHAR  # Which status changed
    - old_value: VARCHAR
    - new_value: VARCHAR
    - changed_at: TIMESTAMP
    - changed_by: VARCHAR
    - change_reason: VARCHAR
Example :
-- Track status transitions for orders
CREATE TABLE order_status_history (
    history_id VARCHAR PRIMARY KEY,
    order_id VARCHAR REFERENCES order(order_id),
    old_status VARCHAR,
    new_status VARCHAR,
    changed_at TIMESTAMP DEFAULT CURRENT_TIMESTAMP,
    changed_by VARCHAR,
    change_reason VARCHAR
);
Difference from**_version**:
_version: Full row snapshots, answers “what was the complete state?”_history: Change events, answers “what specifically changed?”
3. Quality Tables (_quality, _quality_sidecar)
Store data quality metrics and attestations.
Purpose : Answer “How trustworthy is this data?”
Structure :
entity_quality_sidecar:
  attributes:
    - batch_id: VARCHAR (PK)
    - attestation_id: VARCHAR
    - load_timestamp: TIMESTAMP
    - row_count: INTEGER
    - overall_status: VARCHAR      # PASSED, WARNING, FAILED
    - overall_score: DECIMAL
    - completeness_score: DECIMAL
    - uniqueness_score: DECIMAL
    - validity_score: DECIMAL
    - passed_checks: INTEGER
    - failed_checks: INTEGER
    - attestation_json: JSON       # Full attestation detail
Example :
-- Quality sidecar for transactions
CREATE TABLE fct_transactions_quality_sidecar (
    batch_id VARCHAR PRIMARY KEY,
    load_timestamp TIMESTAMP,
    row_count INTEGER,
    overall_status VARCHAR,
    overall_score DECIMAL(5,4),
    completeness_score DECIMAL(5,4),
    uniqueness_score DECIMAL(5,4),
    total_checks INTEGER,
    passed_checks INTEGER,
    attestation_json JSON
);

-- Query: "Should I trust today's data?"
SELECT batch_id, overall_status, overall_score
FROM fct_transactions_quality_sidecar
WHERE load_timestamp >= CURRENT_DATE
  AND overall_status = 'PASSED';
4. Log Tables (_log)
Track operational events: loads, deployments, executions.
Purpose : Answer “What happened during processing?”
Structure :
entity_load_history:
  attributes:
    - load_id: VARCHAR (PK)
    - entity_id: VARCHAR (FK)
    - batch_id: VARCHAR
    - load_start: TIMESTAMP
    - load_end: TIMESTAMP
    - rows_inserted: INTEGER
    - rows_updated: INTEGER
    - rows_deleted: INTEGER
    - status: VARCHAR              # SUCCESS, FAILED, PARTIAL
    - error_message: VARCHAR
Example :
-- Deployment log for models
CREATE TABLE model_deployment_log (
    deployment_id VARCHAR PRIMARY KEY,
    model_id VARCHAR,
    version_tag VARCHAR,
    environment VARCHAR,
    deployed_at TIMESTAMP,
    deployed_by VARCHAR,
    deployment_ticket VARCHAR,
    status VARCHAR
);
5. Audit Tables (_audit)
Track who accessed or modified data and when.
Purpose : Answer “Who did what and when?” (compliance, security)
Structure :
entity_audit:
  attributes:
    - audit_id: VARCHAR (PK)
    - entity_id: VARCHAR (FK)
    - action: VARCHAR              # SELECT, INSERT, UPDATE, DELETE
    - performed_by: VARCHAR
    - performed_at: TIMESTAMP
    - client_ip: VARCHAR
    - session_id: VARCHAR
    - affected_rows: INTEGER
6. Configuration Tables (_config, _def)
Store runtime parameters and definitions.
Purpose : Answer “How should this entity behave?”
Structure :
entity_config:
  attributes:
    - config_id: VARCHAR (PK)
    - entity_id: VARCHAR (FK)
    - config_key: VARCHAR
    - config_value: VARCHAR
    - effective_from: TIMESTAMP
    - effective_to: TIMESTAMP
Example :
-- PIT generation configuration
CREATE TABLE dim_customer_pit_config (
    config_id VARCHAR PRIMARY KEY,
    entity_id VARCHAR,
    pit_generation_enabled BOOLEAN,
    snapshot_frequency VARCHAR,
    retention_days INTEGER
);
Naming Conventions
MDDE follows consistent naming patterns for sidecar tables:
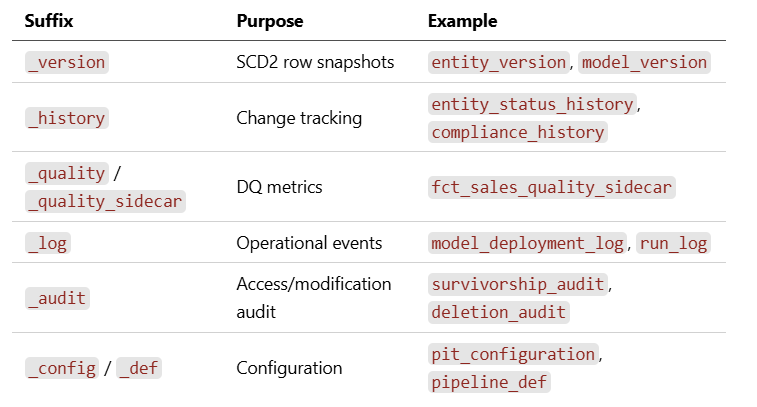
Full Naming Pattern :
{main_entity}_{sidecar_type}
Examples:
customer→customer_version,customer_history,customer_quality_sidecarfct_orders→fct_orders_version,fct_orders_load_historydim_product→dim_product_status_history,dim_product_quality_sidecar
Multiple Sidecars per Main Table
A single main table can have multiple sidecar tables, each serving different purposes:
                    ┌─────────────────────────┐
                    │      dim_customer       │
                    │  (Main Business Table)  │
                    │                         │
                    │  customer_id (PK)       │
                    │  name                   │
                    │  email                  │
                    │  segment                │
                    └───────────┬─────────────┘
                                │
         ┌──────────────────────┼──────────────────────┐
         │                      │                      │
         ▼                      ▼                      ▼
┌─────────────────┐   ┌─────────────────┐   ┌─────────────────┐
│ dim_customer_   │   │ dim_customer_   │   │ dim_customer_   │
│ version         │   │ status_history  │   │ quality_sidecar │
│                 │   │                 │   │                 │
│ Full SCD2       │   │ Segment changes │   │ DQ scores per   │
│ snapshots       │   │ over time       │   │ load batch      │
└─────────────────┘   └─────────────────┘   └─────────────────┘
         │
         ▼
┌─────────────────┐
│ dim_customer_   │
│ load_history    │
│                 │
│ ETL execution   │
│ statistics      │
└─────────────────┘
MDDE’s Internal Model Example :
The entity table (core metadata) has multiple sidecars:

Implementation Patterns
Pattern 1: Foreign Key Reference
The simplest pattern — sidecar references main table:
CREATE TABLE customer_version (
    version_id VARCHAR PRIMARY KEY,
    customer_id VARCHAR NOT NULL REFERENCES customer(customer_id),
    -- versioned attributes...
);
Pros : Strong referential integrity Cons : Cannot create sidecar record before main record exists
Pattern 2: Loose Coupling
Sidecar stores the reference without FK constraint:
CREATE TABLE customer_quality_sidecar (
    batch_id VARCHAR PRIMARY KEY,
    entity_name VARCHAR NOT NULL,  -- 'customer'
    -- quality metrics...
);
Pros : Sidecar can exist independently, works for external data Cons : No referential integrity guarantee
Pattern 3: Composite Key Reference
For sidecars that track attributes:
CREATE TABLE attribute_propagation_history (
    history_id VARCHAR PRIMARY KEY,
    entity_id VARCHAR NOT NULL,
    attribute_id VARCHAR NOT NULL,
    -- history details...
    FOREIGN KEY (entity_id, attribute_id)
        REFERENCES attribute(entity_id, attribute_id)
);
Pattern 4: JSON Sidecar Column
Sometimes a full sidecar table is overkill. Embed as JSON:
CREATE TABLE fct_transactions (
    transaction_id VARCHAR PRIMARY KEY,
    amount DECIMAL(18,2),
    -- business columns...
    -- Embedded sidecar as JSON
    _quality_attestation JSON,
    _lineage_metadata JSON
);
Pros : No join needed, data travels together Cons : Harder to query, index, and maintain
When to Use Sidecar Tables
Use Sidecars When:
- Separation of concerns — Operational metadata shouldn’t pollute business data
- Different lifecycles — You may want to archive/purge sidecars independently
- Different access patterns — Consumers rarely need metadata
- Compliance requirements — Audit trails must be immutable
- Multiple metadata types — One main table needs version + quality + audit
Avoid Sidecars When:
- Simple audit columns suffice —
created_at,updated_atcover your needs - Performance critical — Every join adds latency
- Metadata always needed — If consumers always need quality scores, embed them
- Low volume — Overhead not justified for small tables
MDDE’s Sidecar Implementation
MDDE uses sidecars extensively in its internal metadata model:
Versioning Sidecars
models/versioning/entities/
├── attribute_version/      # Attribute definition history
├── entity_version/         # Entity definition history
├── model_version/          # Model definition history
├── relationship_version/   # Relationship definition history
├── schema_version/         # Schema definition history
├── object_version/         # Generic object versioning
├── change_log/             # Change event log
├── deletion_audit/         # Soft delete tracking
└── domain_version_history/ # Domain value changes
History Sidecars
models/governance/entities/
├── entity_status_history/  # Lifecycle status transitions
├── compliance_history/     # Compliance check results
├── spec_history/           # Specification change history
└── survivorship_audit/     # MDM survivorship decisions

models/operations/entities/
├── entity_load_history/    # ETL load statistics
├── effectivity_history/    # Effectivity period changes
├── quality_metric_history/ # DQ metric time series
└── quality_kpi_history/    # Aggregated quality KPIs
Log Sidecars
models/operations/entities/
├── model_deployment_log/   # Deployment events
├── run_log/                # Pipeline execution log
└── sql_generation_run/     # SQL generation events

models/work/entities/
└── work_action_log/        # User action audit
Quality Sidecar in Detail
The quality sidecar pattern (ADR-371) deserves special attention as it enables data trust decisions :
-- Producer creates quality attestation
INSERT INTO fct_transactions_quality_sidecar (
    batch_id,
    load_timestamp,
    row_count,
    overall_status,
    overall_score,
    completeness_score,
    uniqueness_score,
    attestation_json
) VALUES (
    'batch_20260301_001',
    '2026-03-01 10:00:00',
    1500000,
    'PASSED',
    0.9875,
    0.9950,
    1.0000,
    '{"checks": [...], "environment": "PROD", "producer_version": "v2.1.0"}'
);

-- Consumer queries quality before using data
SELECT t.*, q.overall_status, q.overall_score
FROM fct_transactions t
JOIN fct_transactions_quality_sidecar q ON t.batch_id = q.batch_id
WHERE q.overall_status = 'PASSED'
  AND q.overall_score >= 0.95;
Quality travels with data — Consumers can make informed decisions about data trustworthiness.
Best Practices
1. Consistent Naming
Follow the {main_entity}_{sidecar_type} pattern religiously:
✅ customer_version
✅ customer_status_history
✅ customer_quality_sidecar

❌ customer_hist           # Unclear abbreviation
❌ version_customer        # Wrong order
❌ tbl_customer_versions   # Hungarian notation
2. Common Columns
Include standard columns in all sidecars:
# Origin tracking
origin_id: VARCHAR      # Source of this record
origin_type: VARCHAR    # yaml_import, sql_parser, api, etc.

# Audit tracking
created_at: TIMESTAMP DEFAULT CURRENT_TIMESTAMP
3. Indexing Strategy
Index the foreign key and common query patterns:
-- Always index the FK
CREATE INDEX idx_customer_version_customer_id
    ON customer_version(customer_id);

-- Index temporal queries
CREATE INDEX idx_customer_version_valid_from
    ON customer_version(valid_from);

-- Index current record lookup
CREATE INDEX idx_customer_version_current
    ON customer_version(customer_id, is_current)
    WHERE is_current = TRUE;
4. Retention Policies
Define retention independently for sidecars:
retention_policies:
  customer:
    retention: forever          # Business data kept indefinitely
  customer_version:
    retention: 7_years          # Regulatory requirement
  customer_quality_sidecar:
    retention: 90_days          # Operational data, shorter retention
  customer_load_history:
    retention: 30_days          # Debug data, shortest retention
5. Documentation
Document the relationship in metadata:
# customer.yaml
entity:
  name: customer
  sidecars:
    - type: version
      table: customer_version
      purpose: SCD2 history for regulatory compliance
    - type: quality
      table: customer_quality_sidecar
      purpose: DQ attestation per load batch
    - type: history
      table: customer_status_history
      purpose: Segment transition audit
Querying Sidecars
Point-in-Time Query (Version Sidecar)
-- What was customer 123's segment on Jan 1, 2026?
SELECT cv.segment
FROM customer_version cv
WHERE cv.customer_id = '123'
  AND cv.valid_from <= '2026-01-01'
  AND (cv.valid_to > '2026-01-01' OR cv.valid_to IS NULL);
Change History Query (History Sidecar)
-- Show all segment changes for customer 123
SELECT
    old_value AS previous_segment,
    new_value AS new_segment,
    changed_at,
    change_reason
FROM customer_status_history
WHERE entity_id = '123'
  AND status_dimension = 'segment'
ORDER BY changed_at;
Quality-Gated Query (Quality Sidecar)
-- Only use data from batches that passed quality
SELECT t.*
FROM fct_transactions t
JOIN fct_transactions_quality_sidecar q
    ON t.batch_id = q.batch_id
WHERE q.overall_status = 'PASSED'
  AND q.completeness_score >= 0.99;
Load Statistics Query (Log Sidecar)
-- Recent load performance
SELECT
    load_start,
    load_end,
    load_end - load_start AS duration,
    rows_inserted,
    rows_updated,
    status
FROM customer_load_history
WHERE load_start >= CURRENT_DATE - INTERVAL '7 days'
ORDER BY load_start DESC;
Conclusion
Sidecar tables are a powerful pattern for managing metadata without polluting your core data model. By following consistent naming conventions and understanding when to use each sidecar type, you can:
- Keep business tables clean — Only business data in business tables
- Enable time-travel — Full historical audit trails
- Build trust — Quality attestations travel with data
- Debug efficiently — Load logs and operational metrics at your fingertips
- Comply confidently — Immutable audit trails for regulatory requirements
The key insight is that metadata about data is also data — it deserves its own proper schema design, not just extra columns tacked onto the main table.
References
- Sidecar Pattern — Microsoft’s cloud pattern documentation
- Data Engine Thinking — Temporal data patterns
Part of the MDDE series on metadata-driven data engineering.
By Jaco van der Laan on March 5, 2026.
Exported from Medium on March 29, 2026.