Why preventing end-dating and adopting insert-only historization can simplify lineage, improve auditability, and reduce compute costs when combined with PIT tables and surrogate keys.
Summary
Insert-only historization (avoiding end-dating) is an increasingly favored approach in Data Vault and modern warehouse design. It preserves full history, simplifies ingestion, and enhances auditability.
But without smart design (e.g. PIT tables + surrogate keys, or selective end-dating), query performance and compute cost can balloon.

Insert-Only: The Principle
In classical SCD2 and early warehouse design patterns, a record would often be end-dated when a new version arrived — by setting an end date to close the validity window. Data Vault 2.0 and modern insert-only designs reject this:
- No updates. No end-dating.
- Every new version of an entity is a fresh row, with its own validity markers (load timestamp, effective dates, transaction time).
- History is always append-only, preserving a perfect audit trail.
This approach brings auditability and lineage clarity. You never overwrite, you never “fix history” — you just add more.
Reference: Dan Linstedt & Michael Olschimke, Building a Scalable Data Warehouse with Data Vault 2.0 (2016).
Principles & Design Patterns: Insert-Only + SCD2 + PIT Tables
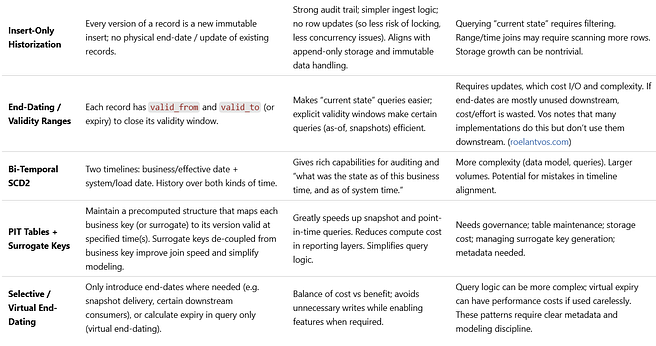
Implementation in Azure Databricks: Performance Implications
When applying insert-only (or selective end-dating) in a system like Databricks with Delta Lake:
- Storage vs Compute: Delta Lake handles large append workloads well; storage cost is low. But join, filter, window, and date-range logic over large historized tables is compute-intensive.
- Partitioning & File Layout: Partition by valid_from (or load date) can help with pruning. Use Z-ordering or clustering to co-locate commonly filtered fields (business key, current flag).
- Use of PIT Tables: By precomputing which version of each record is valid for a given “as-of” date, you can avoid large joins of all history on every query. PIT tables act like indexes.
- Surrogate Keys: Using surrogate keys (e.g. for “customer version row”) reduces key sizes, can help in joins, and avoids natural business keys being large or long strings.
- Avoid Over-engineering: If downstream consumers only require snapshots or only “current state”, then persist end-dating or insert-only with current flags may suffice. For full history, more modeling + queries needed.
What Roelant Vos Teaches Us: “End-Dating, or Not”
Roelant Vos in “End dating, or not, in Data Vault” digs into the trade-offs around end-dating in Satellite and Link-Satellite tables. (roelantvos.com) Key insights:
- Definition & cost: End-dating means giving each record an “expiry” (end-date) when a newer version arrives; the resource cost is not just compute but I/O to write those updates.
- Usage downstream: Many implementations include end-dates in Satellites, but downstream (delivery or snapshot) layers don’t actually use them — so a lot of that work is wasted.
- Insert-only as a default: Roelant Vos recommends preferring insert-only (no persisted end-dates), unless your query/use pattern explicitly requires end-dates. The “virtual” usage of timelines (in queries), or snapshot delivery, can often achieve what end-dating was supposed to do, without physically writing expiry dates.
- Driving keys & timeline types: He also warns that when using driving keys, or when mixing technical vs business timelines (such as load date vs effective date), reports and data views may expect end-dates; so designs need to be explicit in how they will be used.
Roelant Vos’s conclusion: “Implementing a true insert-only Data Vault, with no end dates anywhere whatsoever (derived or persisted), is harder than it initially may appear, but it is definitely achievable. It’s a specific query pattern you will have to apply when performing the date-range joins…”
Literature & Vendor Insights
- Data Vault 2.0 (Dan Linstedt & Michael Olschimke) promotes insert-only satellites (no updates) and immutable record capture.
- Vos highlights how many Data Vault practitioners include end-dates by default but often don’t use them downstream, suggesting wasted cost.
- The “Dual SCD2 + PIT Table” framework shows trade-offs between snapshot vs SCD2 vs PIT-enabled queries. (Medium)
- Kent Graziano’s Agile Data Warehouse Modeling blog shows how PIT tables and surrogate keys can be used to build dimensions from Data Vault without always needing end-dates.
- Other industry blogs (e.g. DLT Hub, QuestDB) describe immutable data design patterns and the balance between incremental change capture vs redundant snapshots.
How We Use This in Model-Driven Data Engineering
In our model-driven approach, we embed these principles directly into metadata and mappings:
- Historization rules are captured in the model, not hidden in ETL code.
- PIT table generation is automated, ensuring efficient query layers.
- Surrogate keys are applied consistently across layers, reducing duplication and complexity.
See my related articles:
- Dual SCD2: The Foundation for True History in Data Warehousing
- PIT Helper Tables: Making Dual SCD2 History Fast and Usable
- https://jacovanderlaan.com/adding-surrogate-keys-to-dual-scd2-tables-to-enable-pit-tables-in-a-data-platform/
Key Takeaways
- Insert-only historization reduces ingestion complexity and increases auditability, but requires PIT tables + surrogate keys for performance.
- End-dating has value in certain cases, but as Vos points out, it is often unused downstream and therefore wasted cost.
- Bi-temporal SCD2 adds rich capability, but with higher operational overhead; apply it when the business case is clear.
- Metadata-driven design ensures consistency and allows automation of historization, PIT creation, and key management.
- Cloud platforms like Databricks thrive on append-only workloads — but compute costs must be optimized.