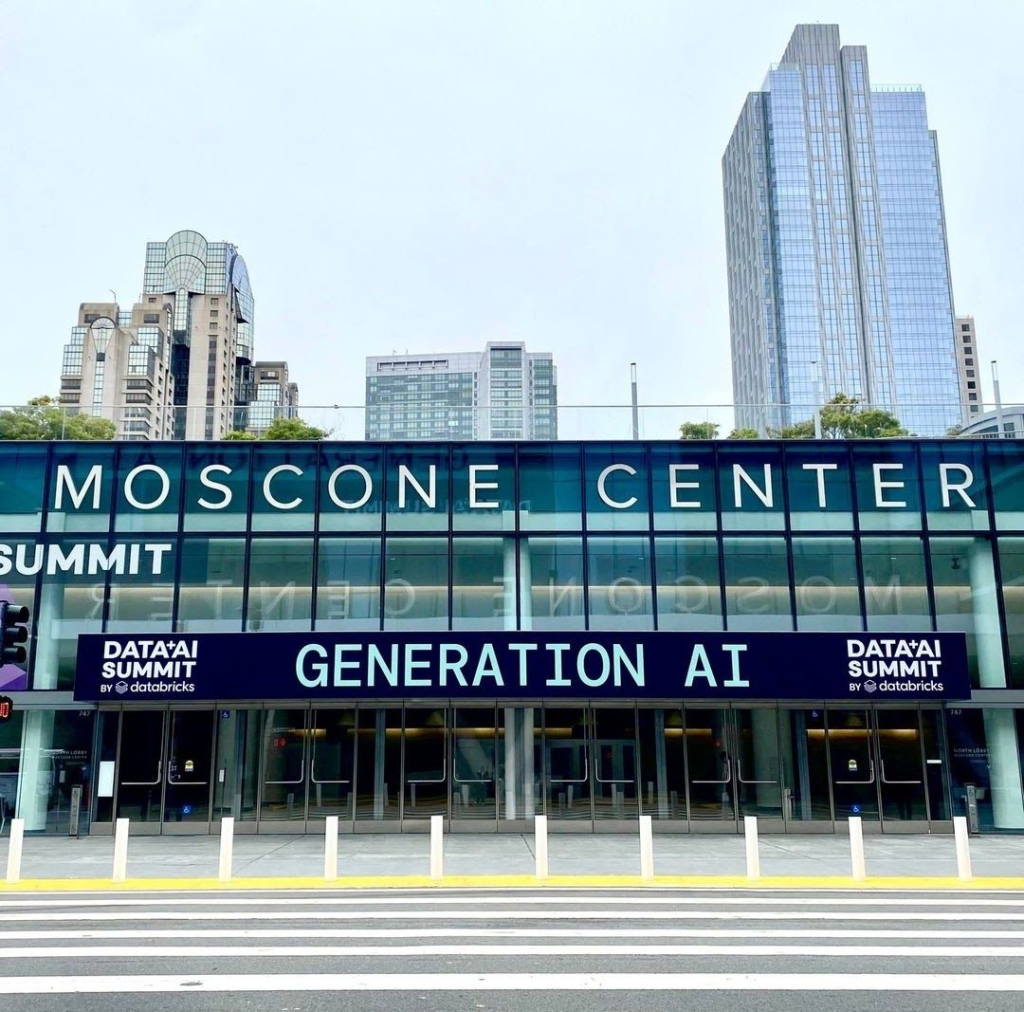
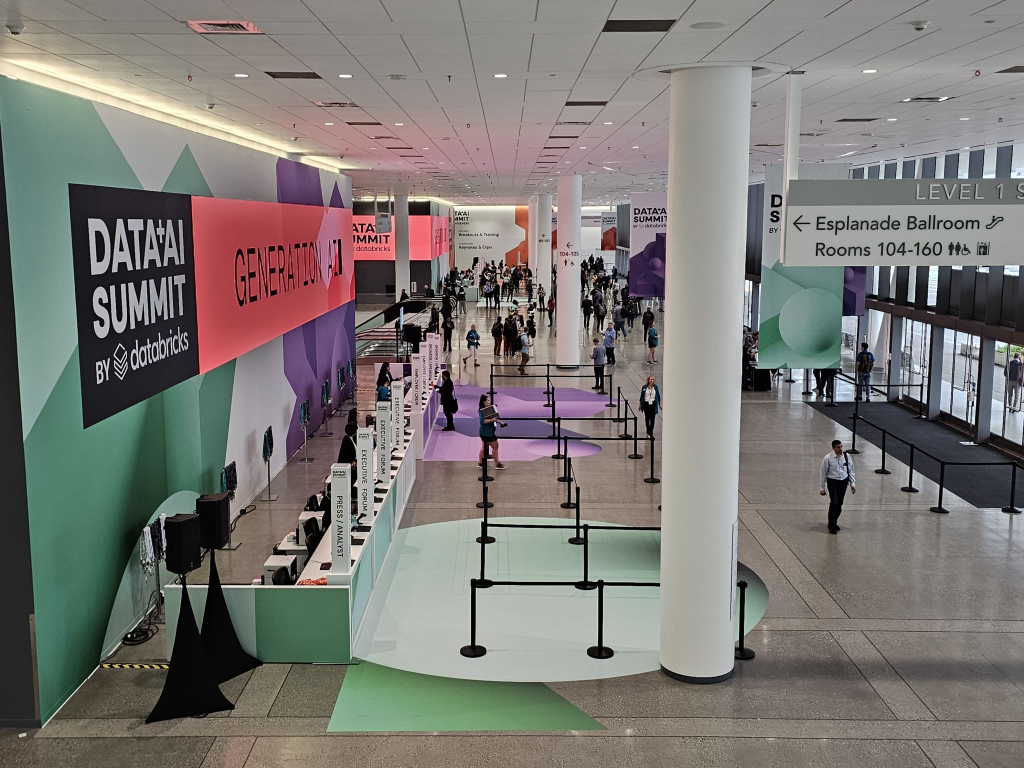
Just returned from the Data + AI Summit 2023 in San Francisco, a leading conference on Lakehouse Data Engineering, Machine Learning and Generative AI with thousands of data experts, hundreds of technical sessions and much more.
In the same week the Snowflake Summit was run in Las Vegas. I attended this conference last year but this year I chose to attend the Data + AI Summit organized by Databricks to get to know both leading cloud data platforms thorougly.
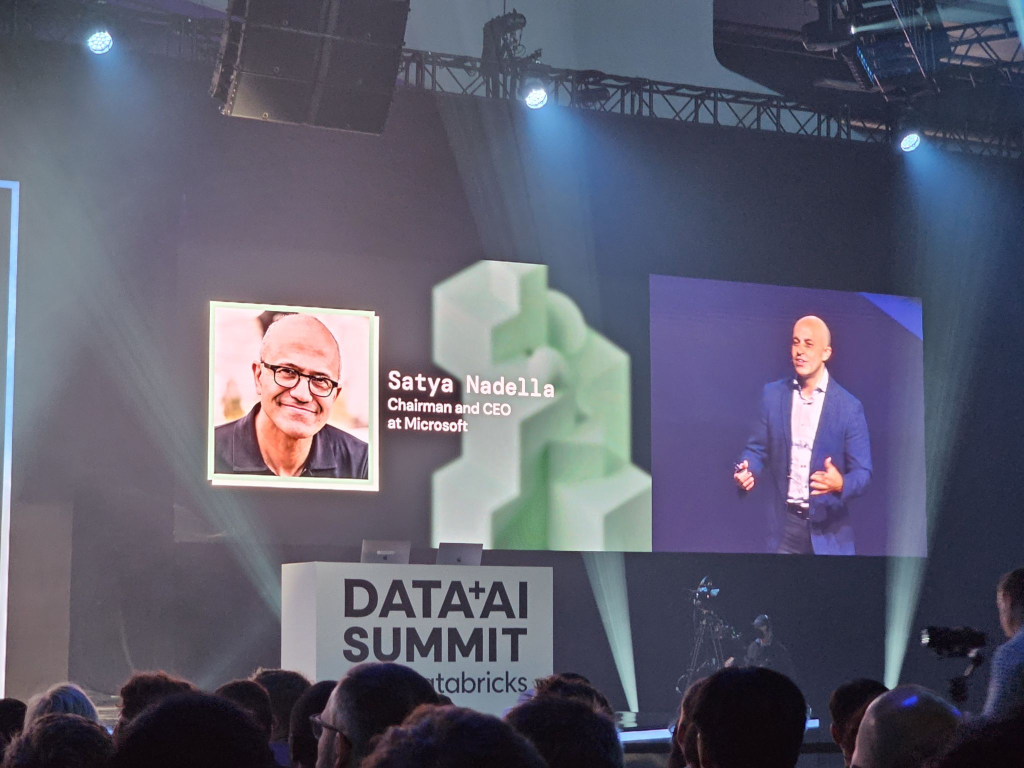
It was a packed program with 2 days of training (Databricks Professional Data Engineer) and 2 days of conference sessions.
I very much enjoyed the energy of this conference especially during the key notes with inspiring speakers and exciting product announcements, LakehouseIQ, Delta Lake 3.0, Lakehouse Federation for Unity Catalog, English SDK for Apache Spark, Lakehouse Monitoring etc. More details on https://lnkd.in/ejKUzYeW.
I attended many interesting sessions, learning more about Lakehouse, Data Engineering, Generative AI, and MLOPS. I also like Databrick’s commitment to an open Lakehouse Delta Lake 3.0 and UniForm removing any concerns about “file format lock-in”.
Delta Lake 3.0 features automatic support for Apache Iceberg and Hudi table formats to enable enterprises to build truly open data lakehouses.
I was also excited about the last session on my schedule as I am always interested how to generate code based on models and metadata (Model Driven Data Engineering).
In this session which was called ‘How to Build a Metadata Driven Data Pipelines with Delta Live Tables’ we learned how you can use metaprogramming to automate the creation and management of Delta Live Tables pipelines at scale.
The end goal is to make it easy to use DLT for large-scale migrations, and other use cases that require ingesting and managing hundreds or thousands of tables, using generic code components and configuration-driven pipelines that can be dynamically reused across different projects or datasets.
Next to the learning I met some great new people from Dutch Databricks customers and consultants like Heineken, ABN-AMRO, Kadaster and Info Support.
Apart from the learning there was also time for some fun! At Wednesday night we were taken to the Chase Center for a Data + AI Party with music featuring 90s hip-hop legends Salt-N-Pepa :-).
On the Sunday before the conference I watched my first baseball game of the San Francisco Giants in the Oracle Stadium.
Finally I was very happy with my contemporary styled citizenM hotels on a 8 minutes walking distance from the conference location (great breakfast & staff!).
Because there were many sessions in parallel I will need some weeks to watch recorded sessions which I could not attend, do some more studying and finally test my knowledge by doing a number of exams. This will keep me busy for the rest of the summer :-).